Cloudflare CEO Projects AI Bot Traffic Will Exceed Human Web Browsing by 1,000x
Matthew Prince outlines HTTP 402 micropayment experiments and default scraping blocks as automated agents surpass human web volume.
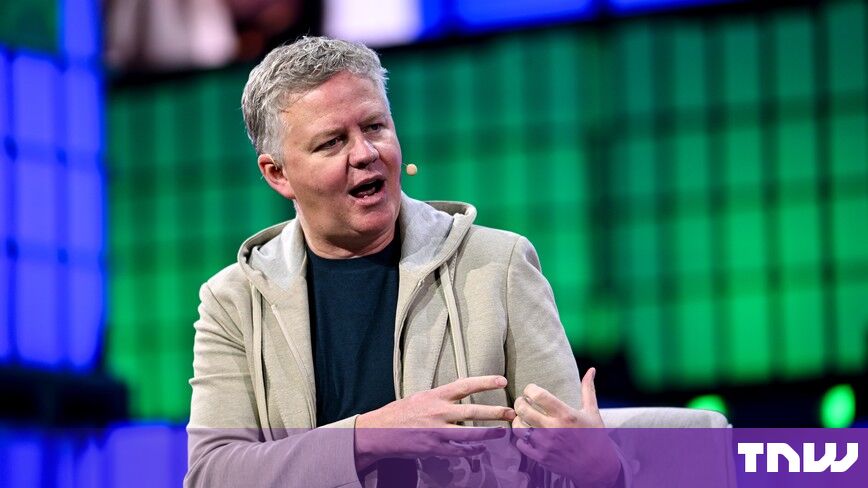
Automated web activity driven by artificial intelligence scrapers and autonomous agents could outstrip human web browsing by 1,000 times within five years, according to Cloudflare Chief Executive Matthew Prince. Speaking on The Verge’s Decoder podcast, Prince stated that non-human web volume had expanded far faster than his previous projections, as reported by The Next Web (https://thenextweb.com/news/cloudflare-matthew-prince-bots-1000x-human-traffic-verge).
Cloudflare, whose network infrastructure sits in front of more than 20% of the web, has repeatedly moved up its timeline for when bot activity would eclipse human visits. At Web Summit last November, Prince estimated that automated queries would overtake human traffic in the second half of 2027. By March, internal data pointed to the first half of 2027, and by May, Cloudflare’s engineers confirmed the crossover had already occurred. While human traffic remains roughly flat, automated scraper and agent activity continues to surge.
The shift challenges the digital advertising model that has funded open web publishing for three decades, Prince noted. Because automated tools do not engage with display ads, Cloudflare is partnering with Coinbase and Stripe to revive HTTP 402, the early internet standard status code designated for "payment required." Under the concept, site operators could charge AI crawlers a fraction of a cent per page visited, with premium content priced higher. Prince said AI developers on the buying side and large publishers on the selling side are both receptive, though Decoder host Nilay Patel noted skepticism in the industry, citing Yahoo CEO Jim Lanzone’s recent remark that micropayments cannot sustain publishers.
In response to data harvesting, Cloudflare initiated a default block on September 15 for its free-tier customers, preventing Google from scraping sites for AI model training unless site owners explicitly opt out. Prince explained the decision was driven by Google’s refusal to distinguish between indexing for search results and scraping for AI model training.
Search providers are facing mounting regulatory pressure to separate those functions. Following a regulatory ruling in the United Kingdom, Google indicated it would provide greater transparency by detailing its crawler's specific activity on individual pages, a protocol it plans to extend beyond the UK. European regulators in Brussels are also surveying publishers regarding the efficacy of Google's AI opt-out tools.
The revenue shift is already surfacing in local media. Prince and his wife own the Park Record, a local newspaper in Park City, Utah, which Prince expects to generate more revenue from AI licensing agreements than from digital advertising this year. In licensing markets, Prince noted that platform data commands wide pricing disparities, with Reddit earning an estimated seven to 14 times more per token than traditional publishers like The New York Times.
Sources
Written by
The Company Wire
Inside the companies building what’s next. Reporting on startups, technology, funding and the people shaping them.