Neo4j Advocates Shared Knowledge Graphs to Prevent Fragmented AI Agent Deployments
Field CTO Jesús Barrasa argues that governed knowledge layers supply necessary business context, auditability, and efficiency across multi-agent systems.
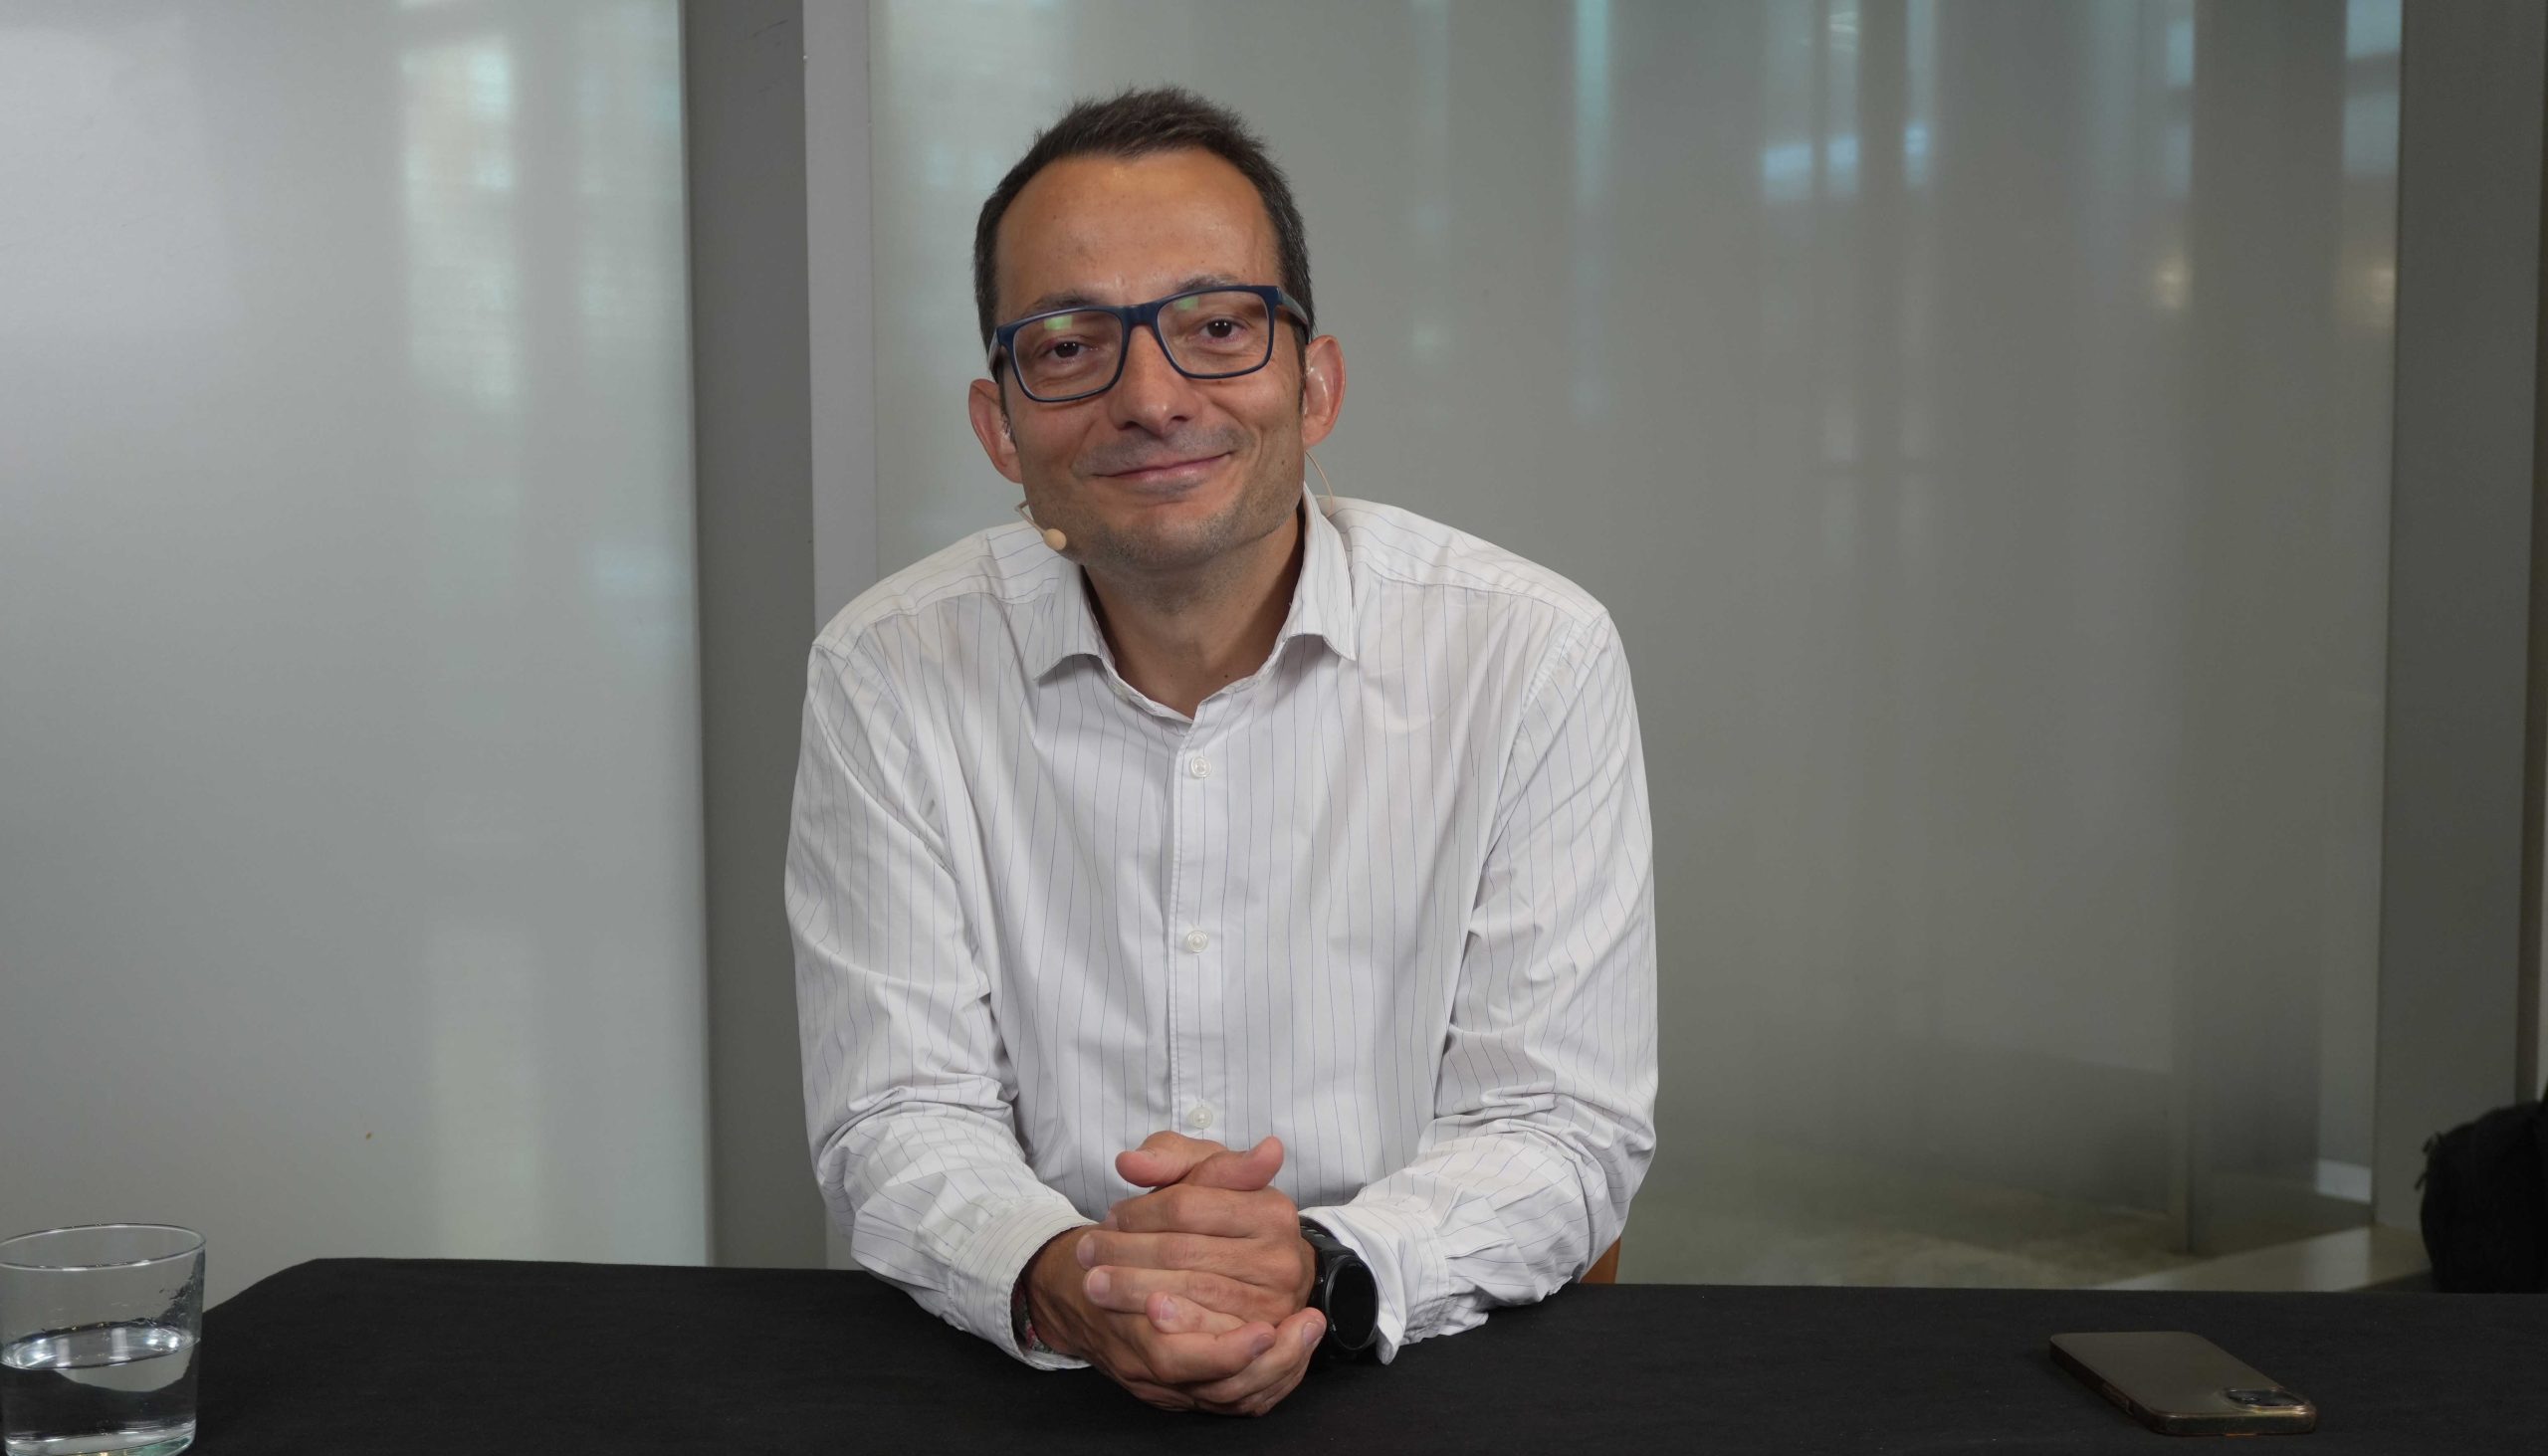
As enterprises expand their deployment of autonomous artificial intelligence agents, graph database maker Neo4j Inc. is making the case for shared knowledge layers to prevent fragmented, inconsistent business logic across software workflows. Speaking at the company’s GraphSummit event in an interview with John Furrier on theCUBE, covered by SiliconANGLE (https://siliconangle.com/2026/09/24/neo4j-makes-case-knowledge-graphs-shared-context-ai-agents-neo4jgraphsummit/), Jesús Barrasa, field chief technology officer of generative AI at Neo4j, emphasized that agents need structured enterprise meaning alongside raw data access.
Organizations have improved at creating individual agents, but performance remains inconsistent across deployments. According to Barrasa, the variation stems from how corporate knowledge is captured and supplied. When engineers embed context directly into isolated prompts and skill definitions for each specific agent, companies risk building duplicate software silos that hold conflicting interpretations of business rules.
Barrasa compared this practice to historical problems in business intelligence reporting, where teams built isolated reports across disparate platforms that produced contradictory numbers. A similar fragmentation occurs when teams deploy point-solution AI agents without standardizing how underlying concepts and policies connect across workflows.
To address these silos, Barrasa advocates for a governed knowledge layer—a structured representation of an enterprise's data assets, concepts, policies, and processes. Beyond enforcing operational consistency, this graph-based layer provides explainability by allowing engineers and auditors to trace the exact data sources and elements an agent used to formulate answers or execute actions.
Rather than attempting an all-encompassing enterprise data model from day one, Barrasa recommended an incremental rollout. Engineering teams should anchor the knowledge graph to an initial use case and align subsequent agent deployments to that baseline. He noted that large language models can accelerate this process by assisting in ontology construction.
Evaluating the financial return on a shared knowledge framework requires tracking multi-project efficiency rather than the output of a single tool. Barrasa stated that organizations should measure the declining build time and cost required for subsequent agents as the shared layer matures, alongside negative metrics such as the operational cost of drift when diverging agents produce conflicting results that require manual reconciliation.
Sources
Written by
The Company Wire
Inside the companies building what’s next. Reporting on startups, technology, funding and the people shaping them.